
Translation memory (TM) is a bilingual database that stores approved source text and its translation as reusable segment pairs. When similar content appears in a new project, a CAT tool retrieves the best match for a linguist to verify or edit. This reduces repeated work, improves consistency, and makes recurring translation faster and more predictable.
Updated October 12, 2026
What Is a Translation Memory?
A translation memory is a structured database of previously translated content. Each record, called a translation unit, normally contains a source-language segment and its approved target-language equivalent. A segment may be a sentence, heading, software string, list item, or short paragraph, depending on the content and segmentation rules.
Translation memory is a core feature of computer-assisted translation (CAT) tools and translation management systems. It does not translate by itself or “remember” language like a person. It retrieves earlier translations whose source text is identical or similar, then gives a professional linguist the context and control needed to reuse them safely.
Trados defines a translation memory as a database of translated sentences, paragraphs, or other text segments. That simple definition matters: TM is stored bilingual evidence from prior work, not automatically generated output.
How Does Translation Memory Work?
Translation memory works by segmenting new source content, comparing each segment with stored translation units, and ranking the results by similarity. A typical workflow has six steps:
- Import: A document, website export, app resource file, or other source enters a CAT tool or TMS.
- Segmentation: The system divides the source into translatable units, usually using punctuation, formatting, and file-specific rules.
- Analysis: Each new segment is compared with the active translation memories and classified as a repetition, context match, exact match, fuzzy match, or new content.
- Retrieval: The most relevant stored target segment appears beside the new source, with differences highlighted where the tool supports them.
- Human review: A linguist checks the source, context, terminology, tags, numbers, and target text, then accepts, edits, or replaces the suggestion.
- Update: Once the translation is approved, the confirmed source-target pair and its metadata are stored for future reuse.
This cycle creates compounding value. Every approved project can improve the leverage available to later updates, provided that the memory is clean, relevant, and properly governed.
What Are Translation Memory Match Types?
A match percentage estimates how similar the current source segment is to a stored source segment. It is not a quality score for the target translation, and percentages are not perfectly comparable across tools because vendors use different matching and penalty rules.
| Match type | Typical score | What it means | Recommended action |
|---|---|---|---|
| Context match | Often 101% or 102% | The source text and stored context match, such as neighboring segments or a string identifier. | Verify context, tags, metadata, and current approval rules. |
| Exact match | 100% | The source text is identical, but its context may differ. | Check whether the meaning, product, locale, or document purpose changed. |
| Near-exact match | Often 95–99% | Small differences may involve numbers, punctuation, spacing, tags, or one word. | Inspect every highlighted difference and update the target. |
| Fuzzy match | Tool-dependent; commonly 50–94% | The source is similar but not identical to a stored segment. | Edit against the complete new source and verify terminology. |
| No useful match | Below the project threshold | No stored segment offers sufficient reuse value. | Translate from scratch or use an approved MT workflow. |
For example, Phrase uses 101% for an in-context match and 100% for an exact source match with different context. Phrase’s context documentation explains why identical source text can need different translations when surrounding segments or string keys change. memoQ’s current match-rate guide likewise separates exact, near-exact, fuzzy, context, and double-context matches.

Why Can a 100% Translation Memory Match Still Need Review?
A 100% match confirms that the source segment is identical to a stored source segment. It does not guarantee that the target is correct for the new context. Short strings such as “Open,” “Charge,” or “Home” can have different meanings in a menu, instruction, legal clause, or product interface.
Review is especially important when the audience, product version, jurisdiction, gender, tone, date, unit, placeholder, or surrounding sentence has changed. Context matches are safer because the tool also compares stored contextual information, but critical or regulated content should still follow the project’s defined human-review and quality-assurance process.
What Are the Benefits of Translation Memory?
The business value of translation memory is strongest when content repeats across product releases, manuals, websites, contracts, support articles, catalogs, and software versions.
- Faster delivery: Linguists begin with approved reusable content instead of translating every segment from zero.
- More consistent language: Earlier wording, tone, product names, and recurring warnings remain aligned across files and teams.
- More predictable estimates: Pre-project analysis separates repetitions, match bands, and new words before production begins.
- Lower recurring effort: Exact and high-quality fuzzy matches usually require less work than new content, which may support transparent discounts.
- Better scalability: A shared, governed memory helps multiple linguists and vendors reuse the same approved material.
- Stronger continuity: Linguistic knowledge can survive staff, vendor, and technology changes when the client controls exports and metadata.
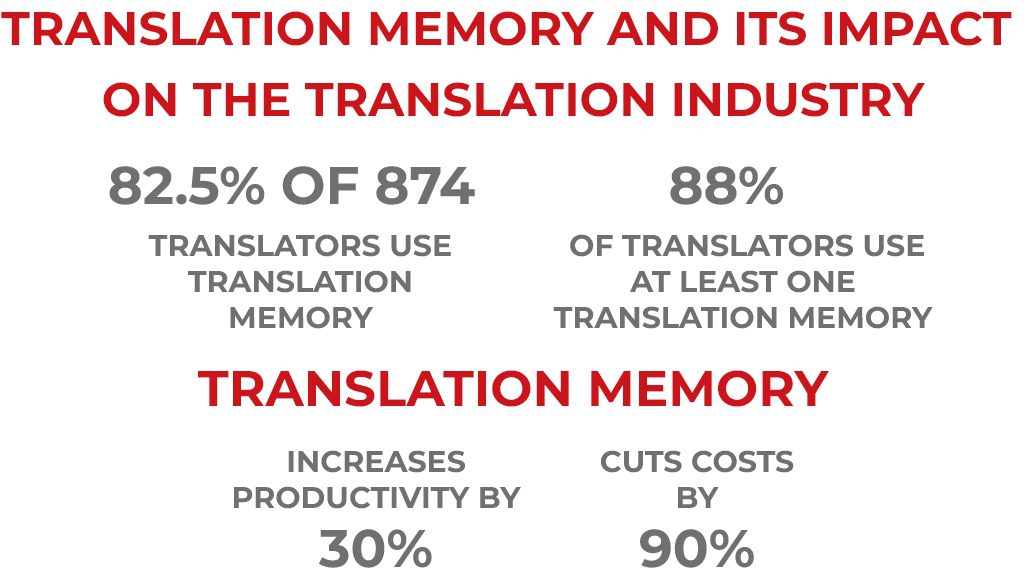
Translation memory does not guarantee savings on every project. Highly creative campaigns, one-off content, poorly standardized source writing, and unrelated subject domains may produce limited useful matches. Savings also depend on the pricing model, match thresholds, review requirements, and the quality of the stored data.
Translation Memory vs. Machine Translation: What Is the Difference?
Translation memory retrieves an existing translation; machine translation generates a new one. Both may appear in the same CAT editor, but their origin, risk, and review logic are different.
| Aspect | Translation memory | Machine translation |
|---|---|---|
| Output source | Stored bilingual segments from earlier work | A new translation generated by an MT model |
| Best use | Recurring, revised, and repetitive content | New content with little or no TM leverage |
| Main strength | Reuse and consistency | Rapid first-draft coverage |
| Main risk | Outdated, incorrect, or contextually unsuitable legacy content | Inaccurate, incomplete, inconsistent, or fabricated wording |
| Quality control | Review according to match type, context, and content risk | Human post-editing and validation according to purpose and risk |

Modern workflows often use a cascade: context and exact TM matches first, fuzzy matches second, machine translation for suitable unmatched content, and professional review throughout. The correct sequence and thresholds should reflect the content’s impact. A product description and a medical safety warning should not share the same automation policy.
Translation Memory vs. Termbase, CAT Tool, and TMS
| Resource | What it stores or manages | Primary purpose |
|---|---|---|
| Translation memory | Source-and-target segment pairs plus metadata | Reuse approved translations |
| Termbase or glossary | Approved concepts, terms, definitions, usage notes, and equivalents | Control terminology at word or phrase level |
| CAT tool | TM, terminology, file segmentation, editor, and QA functions | Provide the linguist’s translation workspace |
| TMS | Projects, workflows, users, vendors, integrations, reporting, and linguistic assets | Coordinate the complete translation operation |
These components complement one another. A TM may retrieve a full approved sentence, while a termbase flags the required product term inside it. The CAT tool presents both resources to the linguist, and the TMS controls how content, users, approvals, and assets move through the wider workflow. See our comparison of CAT tools and TMS platforms for more detail.
How Should You Build and Maintain a Translation Memory?
A translation memory is only as trustworthy as the content and governance behind it. Large memories are not automatically better; a smaller domain-specific memory of approved translations may outperform a mixed database full of outdated or conflicting entries.
- Separate content by language pair, locale, client, domain, and approval level. Do not mix unrelated legal, medical, marketing, and technical language without a deliberate retrieval policy.
- Control write access. Decide which roles may confirm segments into the working memory and which assets are read-only references.
- Store useful metadata. Include origin, project, product, subject, creator, approval status, creation date, and last-change information where the platform supports it.
- Review aligned legacy content. Imported bilingual documents can accelerate setup, but misaligned or unapproved pairs should not enter a production memory unchecked.
- Clean regularly. Remove duplicates, obsolete product language, incorrect targets, broken tags, inconsistent locales, and entries that violate current terminology.
- Back up and test exports. Keep documented recovery procedures and verify that the exported files can be imported into another supported system.
Who Owns the Translation Memory?
Translation memory ownership should be explicit in the contract. For a client-funded program, the client should generally retain access to its dedicated bilingual assets, subject to licensing, confidentiality, third-party, and supplier-agreement terms. Never assume that access, ownership, and portability mean the same thing.
Before appointing a language provider or platform, ask:
- Is our TM dedicated to our account, or is any content pooled?
- Who can read, write, approve, export, and delete entries?
- How are confidentiality, encryption, retention, backups, and access logs handled?
- Can we export the complete memory, including useful metadata, whenever needed?
- What happens to the memory when the relationship ends?
- How are corrections propagated across active and master memories?
Clear ownership and export terms reduce translation-vendor lock-in and preserve the value created through years of approved work.
What Is a TMX File, and Does It Make Translation Memory Portable?
TMX stands for Translation Memory eXchange. It is an XML-based format designed to exchange translation-memory data between tools and vendors with little or no loss of critical information. The TMX 1.4b specification defines how translation units and language-specific segments are represented.
TMX improves portability, but an export is not a perfect guarantee of identical behavior after migration. Tools may differ in how they handle context, tags, custom fields, penalties, segmentation, subsegments, and proprietary metadata. Run a controlled import test, compare match results, and retain the original backup before switching platforms.
When Is Translation Memory Most Useful?
Translation memory provides the greatest return when source content is structured, recurring, and versioned. Strong use cases include:
- product manuals, specifications, and safety documentation;
- software interfaces, apps, websites, and help centers;
- contracts, policies, forms, and recurring compliance content;
- e-commerce catalogs and frequently updated product descriptions;
- training, support, and knowledge-base content;
- annual reports and recurring corporate communications.
It is less decisive for highly original slogans, transcreation, or unrelated one-off material, although concordance search and reference memories may still help linguists find prior wording.
Use Translation Memory Without Inheriting Old Errors
Translation memory turns completed work into a reusable business asset, but reuse must remain accountable. The safest program combines relevant memories, controlled terminology, reliable context, role-based permissions, scheduled maintenance, transparent analysis, and expert review appropriate to the content’s risk.
AsiaLocalize builds and maintains dedicated translation memories within controlled translation workflows for Asian and global markets. Our teams can clean legacy bilingual data, prepare terminology, migrate assets, analyze match leverage, and integrate TM with document translation, software, website, and localization programs. Request a quote to assess your existing linguistic assets and future content pipeline.
Frequently Asked Questions About Translation Memory
Is translation memory the same as machine translation?
No. Translation memory retrieves previously stored bilingual segments, whereas machine translation generates new target text. A modern workflow can use both: TM handles reusable content, MT may draft suitable new content, and linguists review according to context and risk.
What is a fuzzy match in translation memory?
A fuzzy match is a stored source segment that resembles, but does not exactly match, the current source. The tool assigns a similarity percentage and shows the stored translation as a suggestion. The linguist must identify every difference and edit the target accordingly.
Does translation memory reduce translation costs?
It can reduce effort and cost when content repeats or changes incrementally. Actual savings depend on useful match volume, pricing bands, language pair, review requirements, and memory quality. Ask for both raw word counts and a transparent weighted analysis rather than assuming every match is free.
Can a translation memory contain errors?
Yes. Incorrect, obsolete, misaligned, or context-specific translations can enter a TM and reappear in future projects. Controlled permissions, human approval, metadata, penalties, terminology checks, and scheduled cleaning help prevent legacy errors from spreading.
Can I move a translation memory to another CAT tool?
Usually. Most professional tools support TMX import and export. However, context, tags, custom fields, and proprietary metadata may not transfer identically, so test the migration and compare results before retiring the original system.
Who should own a translation memory?
Ownership should be defined contractually. Clients typically need continuing access to dedicated memories created from their content, along with clear export, security, retention, and end-of-contract provisions. Shared or licensed resources may have different terms.